Best Open-Source Virtual Try-On Models in 2026
Compare the best open-source virtual try-on models in 2026: FASHN VTON v1.5, CatVTON, IDM-VTON, Leffa, OmniTry, and more, with licenses and hardware needs.


Updated October 2026. This guide now covers the open-source virtual try-on models released since our original June 2025 comparison, including FASHN VTON v1.5, Leffa, OmniTry, and general image editors like Qwen-Image-Edit. The head-to-head test results further down are from June 2025 and are labeled as such.
Every virtual try-on (VTON) model promises "photorealistic try-on" and "accurate fit," but quality, hardware needs, and licensing vary wildly. This guide compares the open-source options you can actually download and run in 2026, explains which ones you can use commercially, and shows how the most popular models performed in our hands-on tests.
The short answer
| Model | Released | License | Commercial use | Weights | Best for |
|---|---|---|---|---|---|
| FASHN VTON v1.5 | Jan 2026 | Apache-2.0 | ✅ Yes | ✅ Public | Production-ready try-on on consumer GPUs |
| Qwen-Image-Edit-2509 + try-on LoRA | 2025 | Apache-2.0 (check each LoRA) | ✅ Yes | ✅ Public | Teams already running a general image editor |
| Leffa | Dec 2024 | MIT | ⚠️ License allows it, but check training data terms | ✅ Public | Research and pose-controlled generation |
| OmniTry | Aug 2025 | Apache-2.0 LoRA on a non-commercial base | ❌ No (FLUX.1-Fill-dev base) | ✅ Public | Accessories and jewelry, research |
| CatVTON | Jul 2024 | CC BY-NC-SA 4.0 | ❌ No | ✅ Public | Fast experiments on low-VRAM GPUs |
| IDM-VTON | Mar 2024 | CC BY-NC-SA 4.0 | ❌ No | ✅ Public | Texture and color detail in research |
| OOTDiffusion | Mar 2024 | CC BY-NC-SA 4.0 | ❌ No | ✅ Public | Historical reference |
| StableVITON | Dec 2023 | CC BY-NC-SA 4.0 | ❌ No | ✅ Public | Historical reference |
Licenses checked October 2026. Always read the license and model card before shipping anything to production.
If you need a commercially usable open-source model, FASHN VTON v1.5 is the most direct option. If you just want the best result without hosting anything, a production API like FASHN Try-On Max is the faster route.
What is a virtual try-on model?
A virtual try-on model takes a photo of a person and a photo of a garment, and generates a realistic image of that person wearing the garment.
How does virtual try-on work?
Most early models worked in two steps: they masked out the clothing in the person photo, then used a diffusion model to "inpaint" the new garment into that region, guided by the garment image and sometimes a pose map.
Newer models increasingly skip the mask. Mask-free (or "segmentation-free") models like FASHN VTON v1.5 and OmniTry learn to replace clothing directly, which avoids errors from bad masks and preserves more of the original photo.
What changed since 2025
- The mystery model went open source. Our 2025 comparison included a closed "mystery model" as a benchmark. In January 2026 we released FASHN VTON v1.5 under Apache-2.0, so there's now a production-grade try-on model with a commercial-friendly license.
- Models moved beyond Stable Diffusion 1.5. Newer releases build on FLUX, diffusion transformers, or custom architectures in pixel space instead of fine-tuning SD 1.5 or SDXL.
- Mask-free is becoming the norm. FASHN VTON v1.5, OmniTry, and CatVTON's mask-free version all work without hand-drawn or auto-generated clothing masks.
- General image editors learned try-on. Open-weight editors like Qwen-Image-Edit can place garments on a person with the help of community try-on LoRAs.
- Licensing became the deciding factor. Most research models still use non-commercial licenses, so "open source" rarely means "free to use in your product."
The open-source virtual try-on models worth knowing in 2026
FASHN VTON v1.5
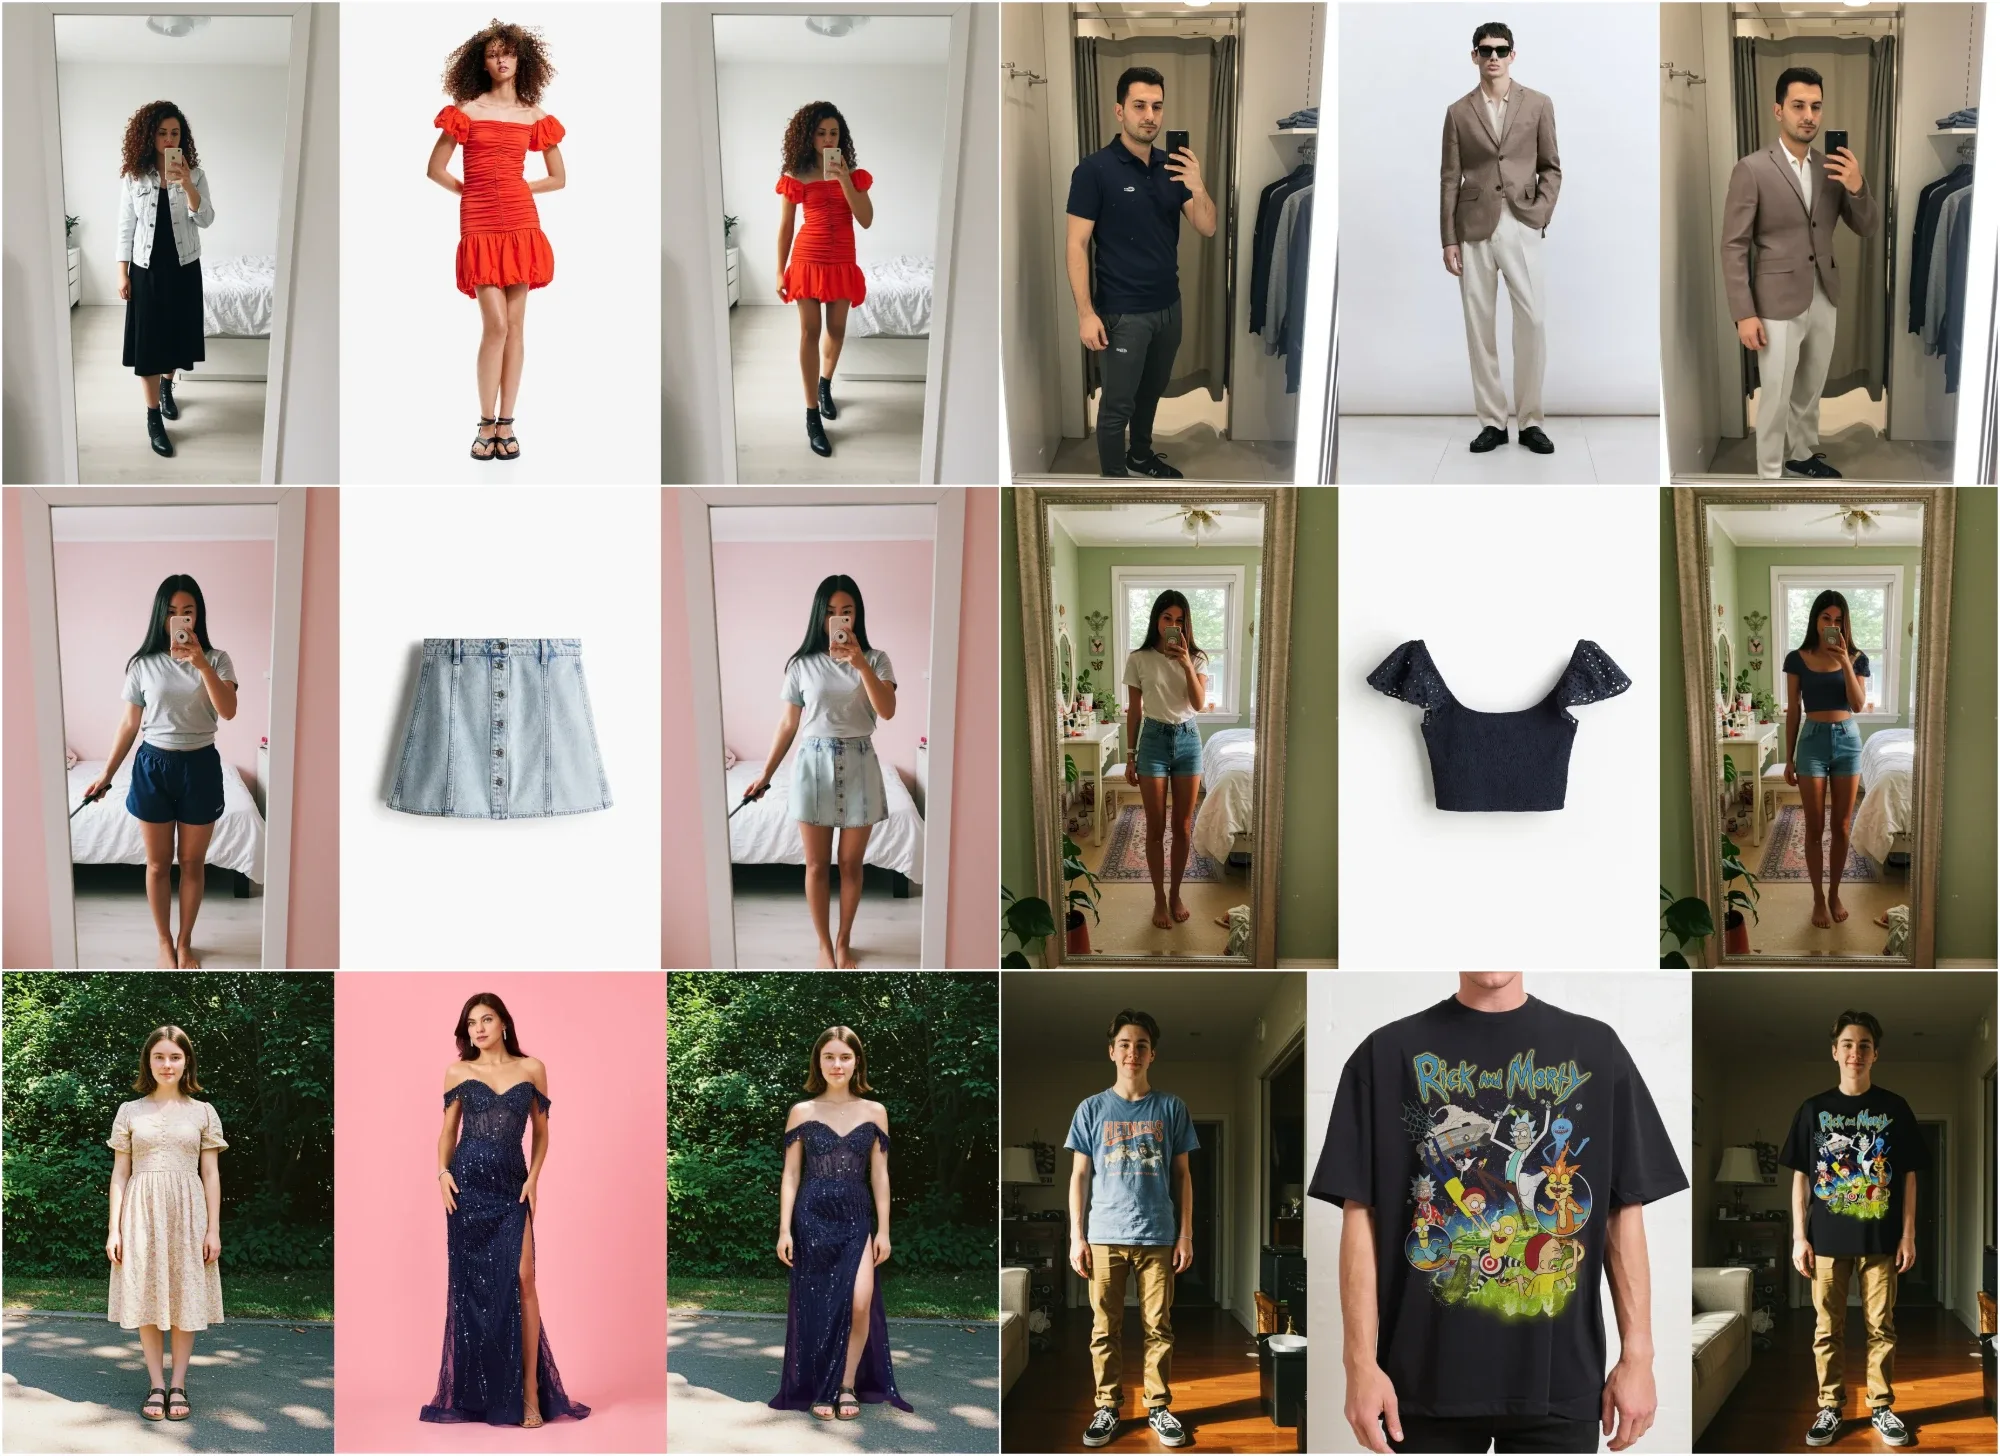
FASHN VTON v1.5 examples. Each set shows the person photo, the garment, and the try-on result.
Model weights | GitHub | Release post
FASHN VTON v1.5 was released in January 2026 under the Apache-2.0 license, which allows commercial use. It's a production-proven try-on baseline that researchers, developers, and product teams can study, extend, and deploy themselves.
- Mask-free, in pixel space. It generates the try-on directly in pixel space, without segmentation masks or a latent autoencoder.
- Lightweight. At 972M parameters (about 2 GB of weights), it runs on consumer GPUs.
- No prompts needed. It takes a person image and a garment image, nothing else.
- Flexible garment inputs. It accepts both on-model photos and flat-lay product shots, for tops, bottoms, and one-pieces.
- Trainable from scratch. It can be retrained from scratch for roughly $5,000 to $10,000 in compute.
Best for: teams that want to self-host a commercially usable try-on model, study a production-proven baseline, or fine-tune for their own catalog.
CatVTON
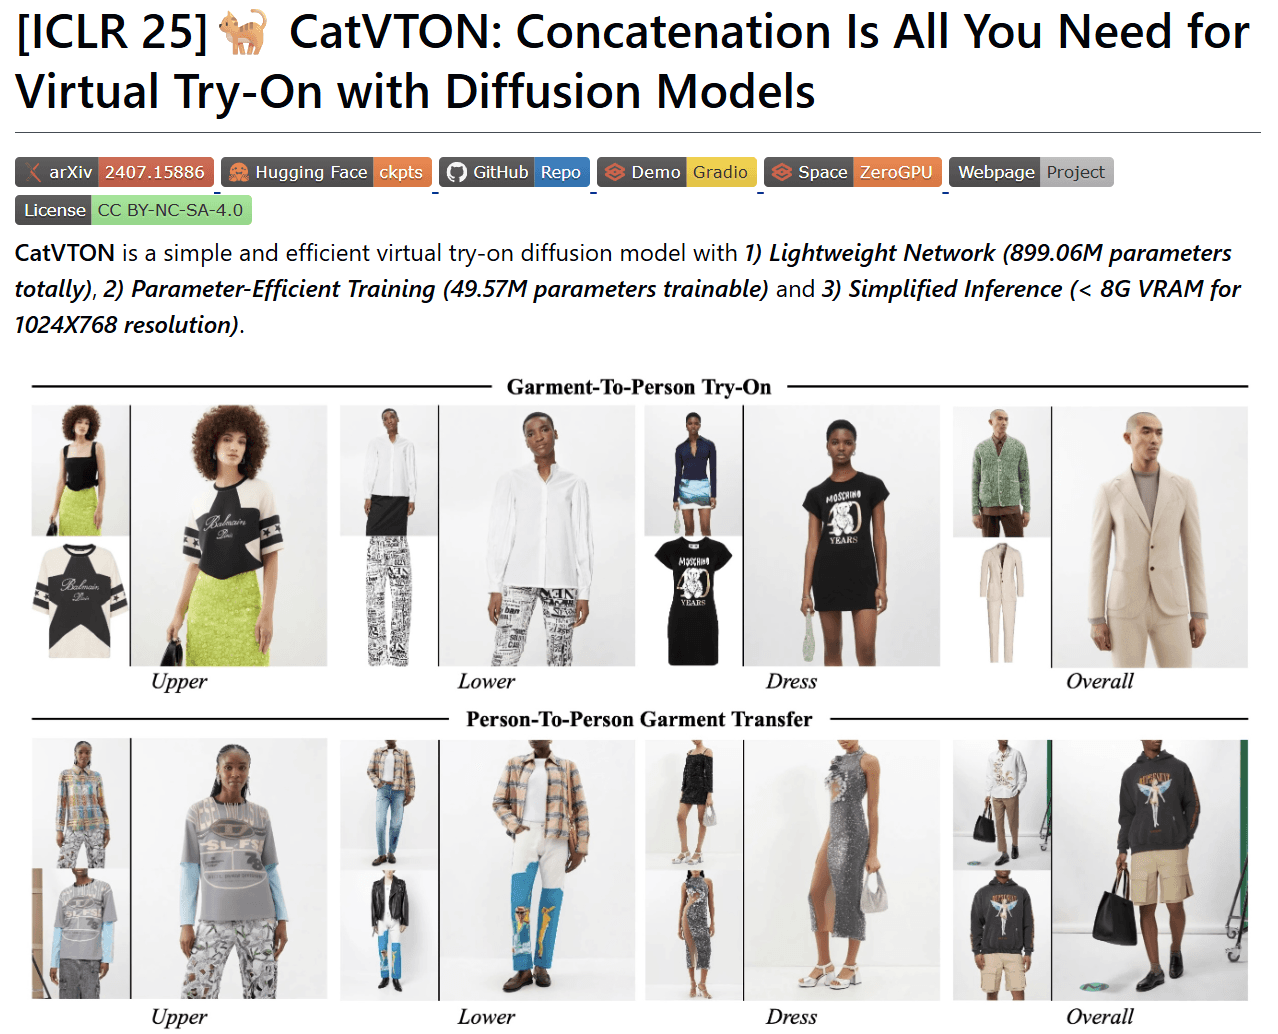
CatVTON: Concatenation Is All You Need for Virtual Try-On with Diffusion Models (GitHub Banner)
CatVTON ("Concatenation Is All You Need") was published on arXiv in July 2024 and accepted to ICLR 2025. It has about 1.9k stars on GitHub. Since our original test, the team has released a mask-free version, an ultra-light LoRA for FLUX.1-Fill-dev, and CatV2TON, which adds video try-on.
How it works: instead of running separate networks for the garment and the person, CatVTON concatenates the garment and person images side by side and passes them through a single compact network. The result is lightweight (899M total parameters, 49M trainable), generates 1024×768 images, and runs on GPUs with less than 8 GB of VRAM.
In plain terms: it tapes the clothing photo next to your photo and lets one small network do everything. That makes it quick on an everyday gaming PC.
License: CC BY-NC-SA 4.0, so no commercial use without a separate agreement.
IDM-VTON
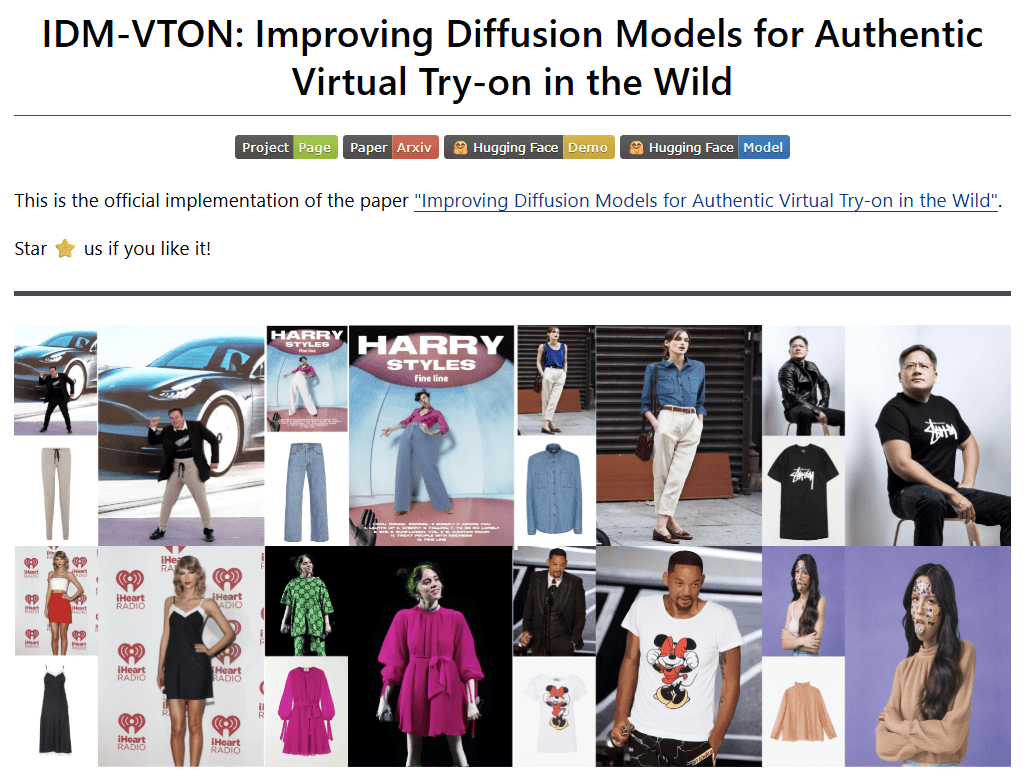
IDM-VTON: Improving Diffusion Models for Authentic Virtual Try-on in the Wild (GitHub Banner)
IDM-VTON was published on arXiv in March 2024 and presented at ECCV 2024. With about 5.2k stars, it's still one of the most widely used open-source try-on models.
How it works: IDM-VTON builds on Stable Diffusion XL with two parallel UNets:
- GarmentNet ❄️ (frozen) extracts fine clothing details like textures, buttons, and patterns.
- TryOnNet 🔥 (trainable) generates the final try-on image.
- An IP-Adapter 🔥 learns from the garment image and guides generation early in the process.
Garment features join TryOnNet through self-attention, and IP-Adapter features through cross-attention.
In plain terms: earlier methods steered a frozen model from the side. IDM-VTON trains the main model directly and uses frozen helpers to extract garment details, which makes the core model better at try-on itself.
License: CC BY-NC-SA 4.0, so no commercial use without a separate agreement.
Leffa
Leffa ("Learning Flow Fields in Attention") was released in December 2024 and accepted to CVPR 2025. It handles both virtual try-on and pose transfer in one framework.
How it works: Leffa adds a regularization loss that guides the model's attention maps toward the right regions of the reference image during training. This reduces the fine-detail distortion that's common in diffusion-based try-on, without adding extra modules at inference time. It generates an image in about 6 seconds on an A100.
License: the code and weights are released under MIT. The released try-on weights are trained on the VITON-HD and DressCode research datasets, so review those datasets' terms before using the weights commercially.
OmniTry
OmniTry was presented at NeurIPS 2025 and released its weights in August 2025. Its goal is to try on any wearable, not just clothing: jewelry, bags, hats, and other accessories, all without masks.
How it works: OmniTry is a LoRA on top of FLUX.1-Fill-dev. It learns where to place an item from large sets of unpaired images, so it doesn't need a mask to know where the item goes.
Hardware: at least 28 GB of VRAM for inference in bfloat16.
License: the OmniTry LoRA is Apache-2.0, but it requires FLUX.1-Fill-dev, which is released under the FLUX.1 [dev] Non-Commercial License. In practice, that makes OmniTry a research option unless you license the base model separately.
Qwen-Image-Edit with try-on LoRAs
Qwen-Image-Edit-2509 | Example try-on LoRA
Not every try-on setup uses a dedicated model. Qwen-Image-Edit-2509 is a 20B-parameter, Apache-2.0 image editor that supports multi-image inputs like "person + product." Community LoRAs, such as FoxBaze's Apache-2.0 try-on LoRA, specialize it for putting one or more garments on a person.
- Pros: a commercial-friendly license, multi-garment outfits, and prompt-based control.
- Cons: at 20B parameters it needs far more GPU memory than dedicated models, results depend heavily on prompts and the LoRA you pick, and garment fidelity isn't guaranteed.
Newer Qwen-Image releases have improved try-on further. In an independent September 2026 test, Qwen-Image 2.1 matched a commercial try-on API on 6 of 8 test pairs, but the same test notes that version uses a research-only license.
Older models: OOTDiffusion and StableVITON
Both models shaped the field, but newer options have overtaken them.
OOTDiffusion (GitHub, AAAI 2025, about 6.6k stars) adapted the two-UNet idea from Google's TryOnDiffusion to Stable Diffusion 1.5: an "Outfitting UNet" studies the garment and shares what it learns with the main UNet at every step. It doesn't use pose information and, in the demos we tested, didn't support lower-body garments. (Google didn't release official TryOnDiffusion code, but you can find our unofficial implementation here.)
StableVITON (GitHub, CVPR 2024, about 1.3k stars) follows the ControlNet approach: it keeps Stable Diffusion 1.5 frozen and trains a copy of its encoder to guide generation with the garment image, a mask, and a DensePose map instead of text.
Both are licensed CC BY-NC-SA 4.0.
Promising, but not open for real use
- Voost (SIGGRAPH Asia 2025) handles both try-on and try-off in a single diffusion transformer, but its weights aren't publicly downloadable and it uses a non-commercial license.
- FitDiT focuses on fine garment detail with a diffusion transformer. Weights require an access request, and the license is CC BY-NC-SA 4.0.
Open-source virtual try-on licensing, explained
Licensing is the biggest practical difference between these models, and the most common source of confusion.
- Permissive (Apache-2.0, MIT): you can use, modify, and ship the model commercially, as long as you keep the license notice. FASHN VTON v1.5 and Qwen-Image-Edit-2509 fall here.
- Non-commercial (CC BY-NC-SA 4.0): free for research and personal projects, but not for products or client work without a separate agreement. CatVTON, IDM-VTON, OOTDiffusion, StableVITON, Voost, and FitDiT fall here.
- Inherited restrictions: a LoRA or fine-tune can have a permissive license while its base model doesn't. OmniTry (Apache-2.0) on FLUX.1-Fill-dev (non-commercial) is the clearest example.
- Training data: a permissive model license doesn't change the terms of the datasets it was trained on. VITON-HD and DressCode, used by many research models, are distributed for research.
Rule of thumb: check the license of the code, the weights, the base model, and the training data before building a product on any of them.
Self-hosting: what to expect
- GPU memory: CatVTON runs on under 8 GB of VRAM, and FASHN VTON v1.5 runs on consumer GPUs. OmniTry needs at least 28 GB, and 20B-parameter editors like Qwen-Image-Edit need even more.
- Preprocessing: older models need clothing masks, pose maps (like DensePose), or both. Mask-free models skip that step, which removes a common source of errors.
- Speed: in our June 2025 tests on A100-class hardware, generation took from about 11 seconds (CatVTON) to 46 seconds (OOTDiffusion).
- Garment coverage: most dedicated models support tops, bottoms, and dresses. Shoes, bags, hats, and jewelry need a model trained for them, like OmniTry, or a production API.
Head-to-head test results (June 2025)
These results are from our original June 2025 comparison of CatVTON, IDM-VTON, and OOTDiffusion. They haven't been rerun for this update, and FASHN VTON v1.5, Leffa, OmniTry, and Qwen-Image-Edit aren't included.
How we tested
We ran each garment through each model 4 times and picked the best of the 4 results. Diffusion models have randomness controlled by a seed, so each run produces slightly different colors, garment placement, and textures. We used each live demo's suggested default settings.
We used these two models for the test:
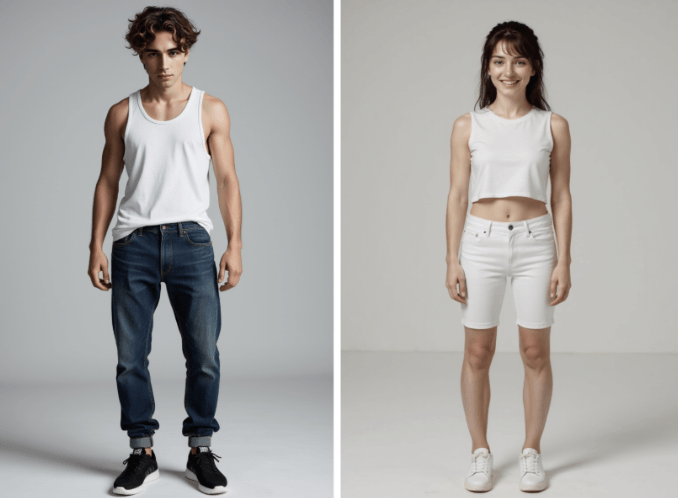
A photo of the two models that we will be using for our comparison.
A few setup notes from the time:
- OOTDiffusion: its Hugging Face Space was broken, so we used a Replicate endpoint. It took 110 seconds to produce 4 results.
- IDM-VTON: the demo's auto-mask only worked on tops, so we masked pants by hand. It also expects a 3:4 aspect ratio, so enable the "crop" option for other image shapes.
- CatVTON: we used the version paired with FLUX.1-dev Fill, which reported state-of-the-art results on VITON-HD in November 2024, with the creator's suggested 30 steps and 30 guidance scale.
Round 1: Puffer jacket
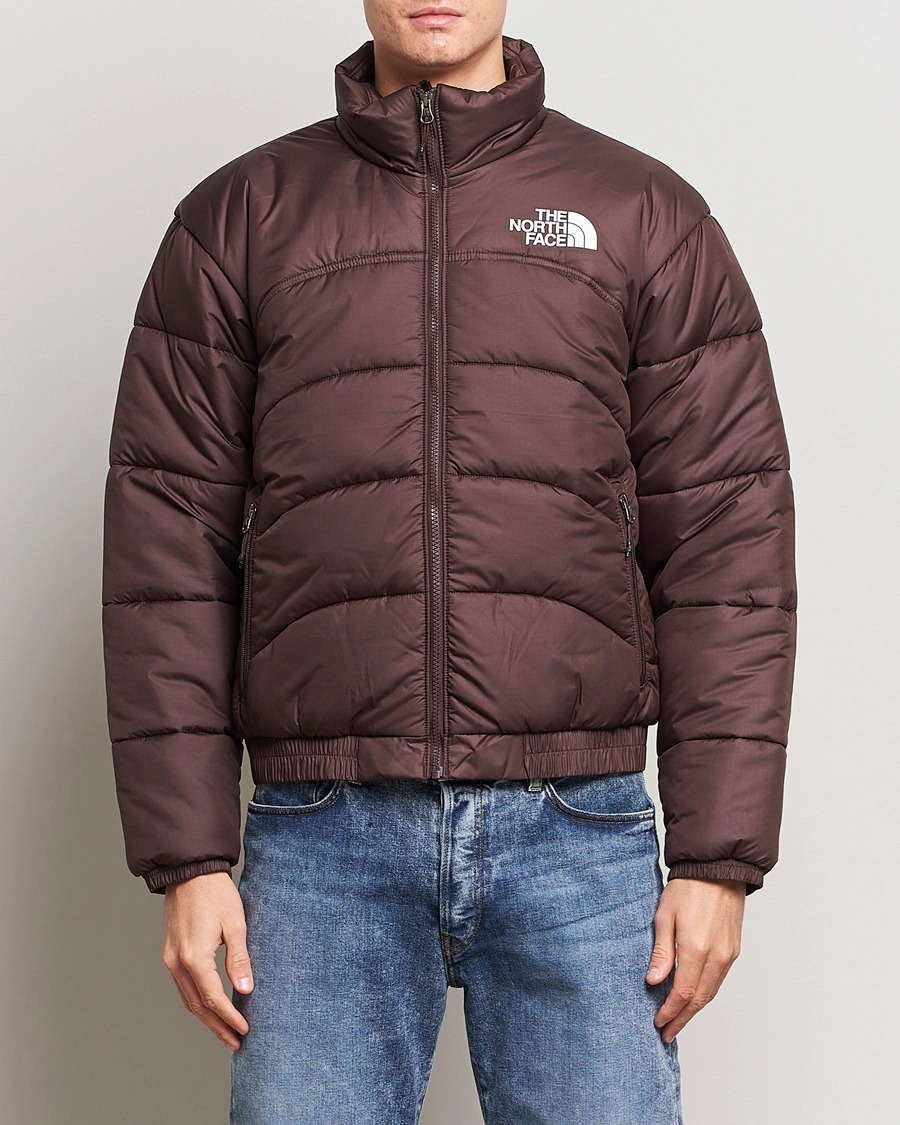
OOTDiffusion performed the weakest. CatVTON was more accurate and reproduced all 5 padding sections, while IDM-VTON generated only 4. IDM-VTON did stand out with more detailed, realistic textures.

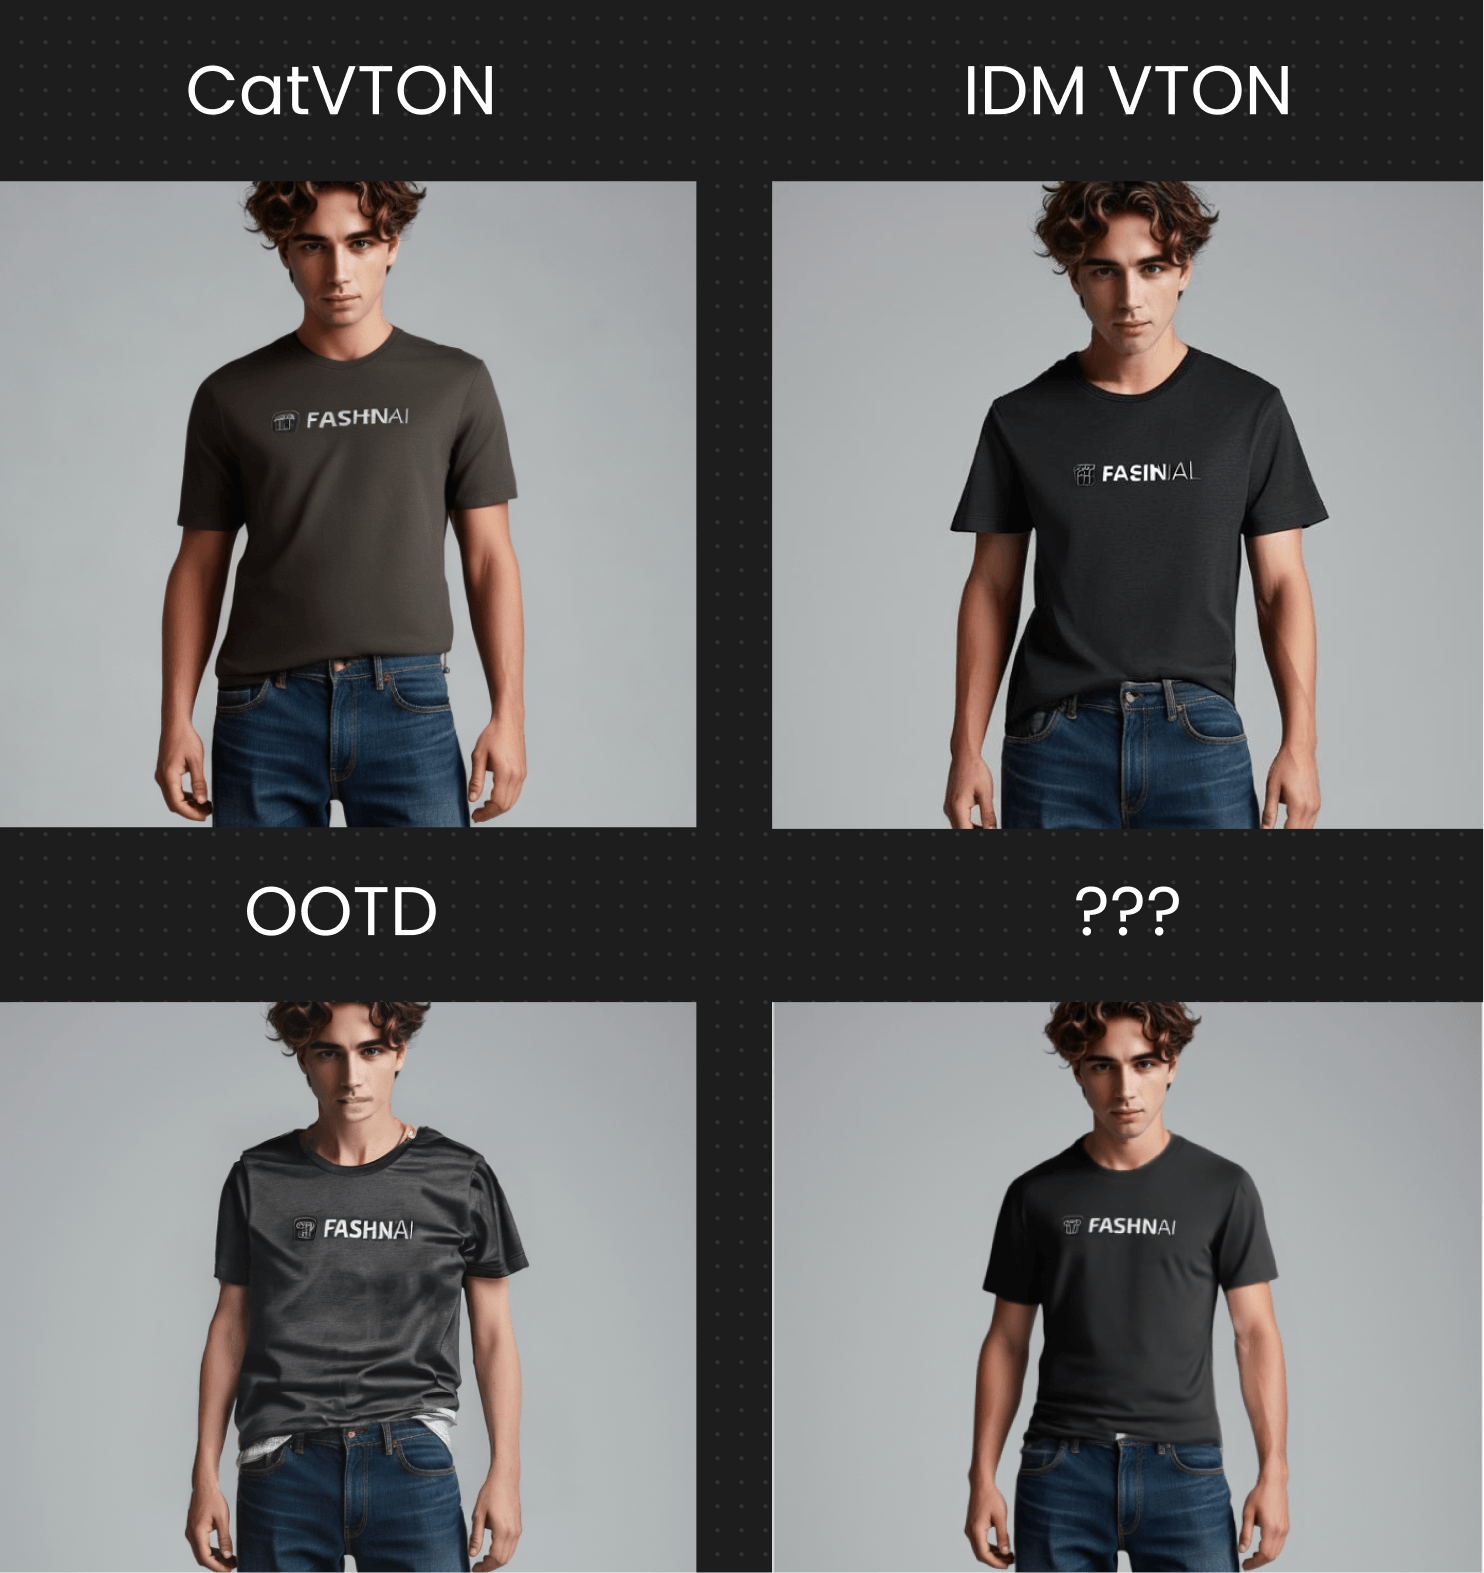
Round 2: Plain black T-shirt with a small graphic
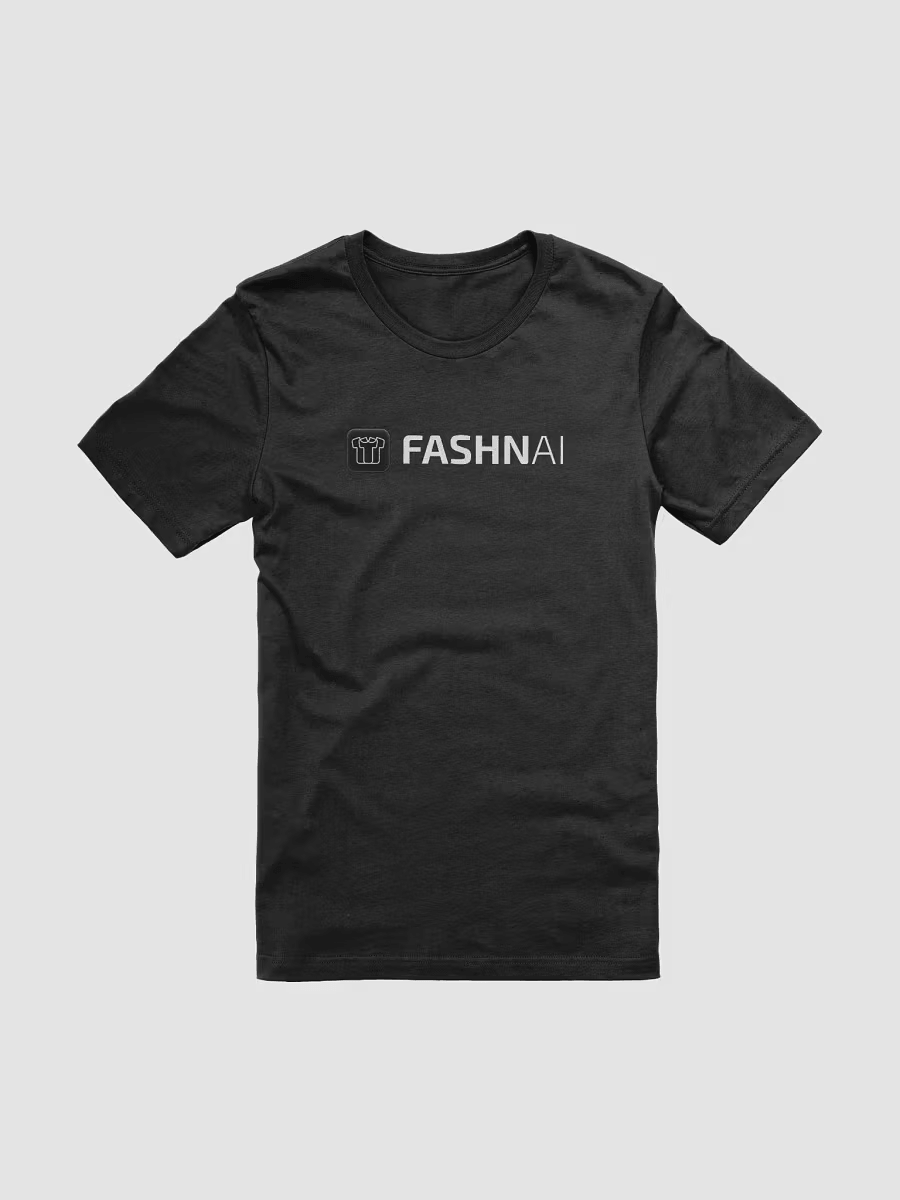
A plain black graphic t-shirt flat lay with the text "FASHN AI"
OOTDiffusion still struggled despite rendering the text correctly. CatVTON handled the text better, but IDM-VTON again had more accurate colors and a more natural fabric look.
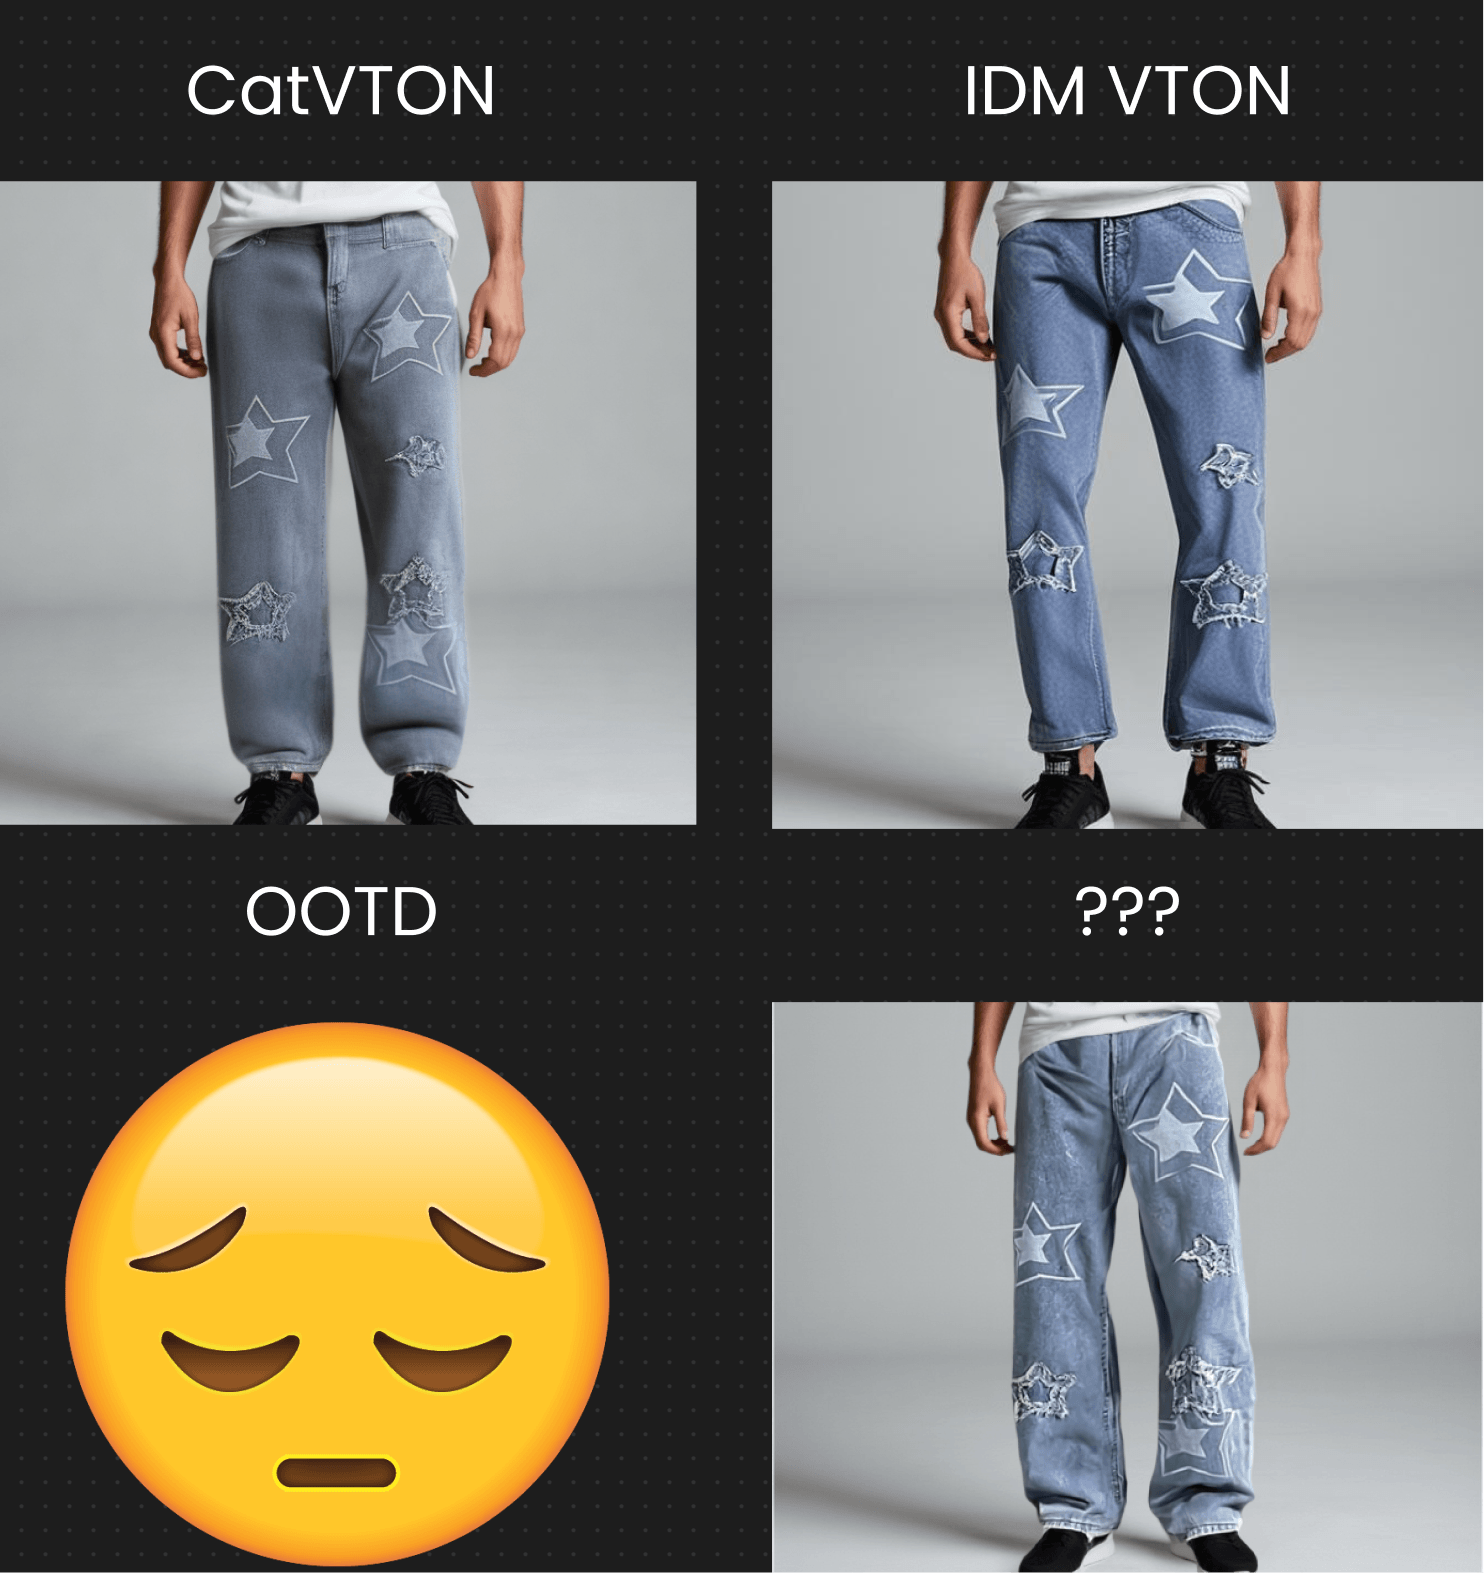
Round 3: Baggy jeans with a complex design
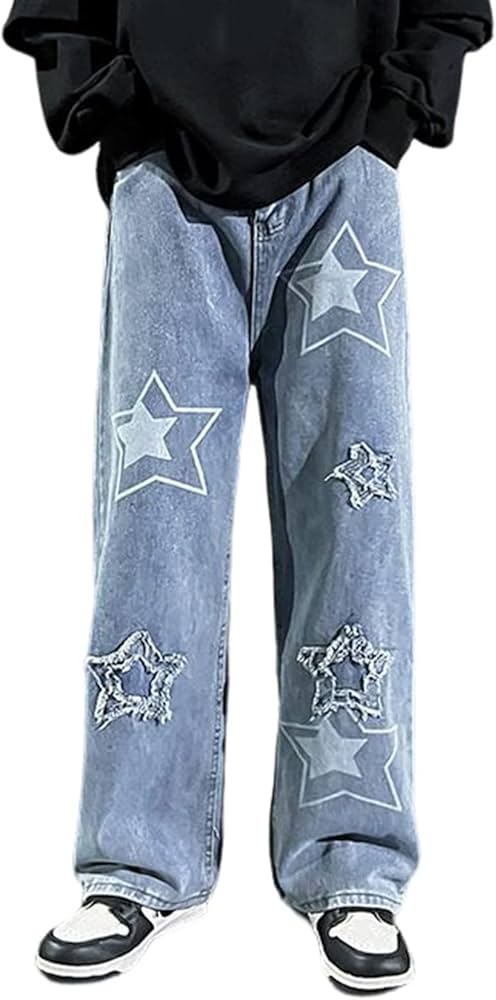
The OOTDiffusion demos didn't support lower-body garments, so it's excluded here. CatVTON delivered the best result among the open-source models.
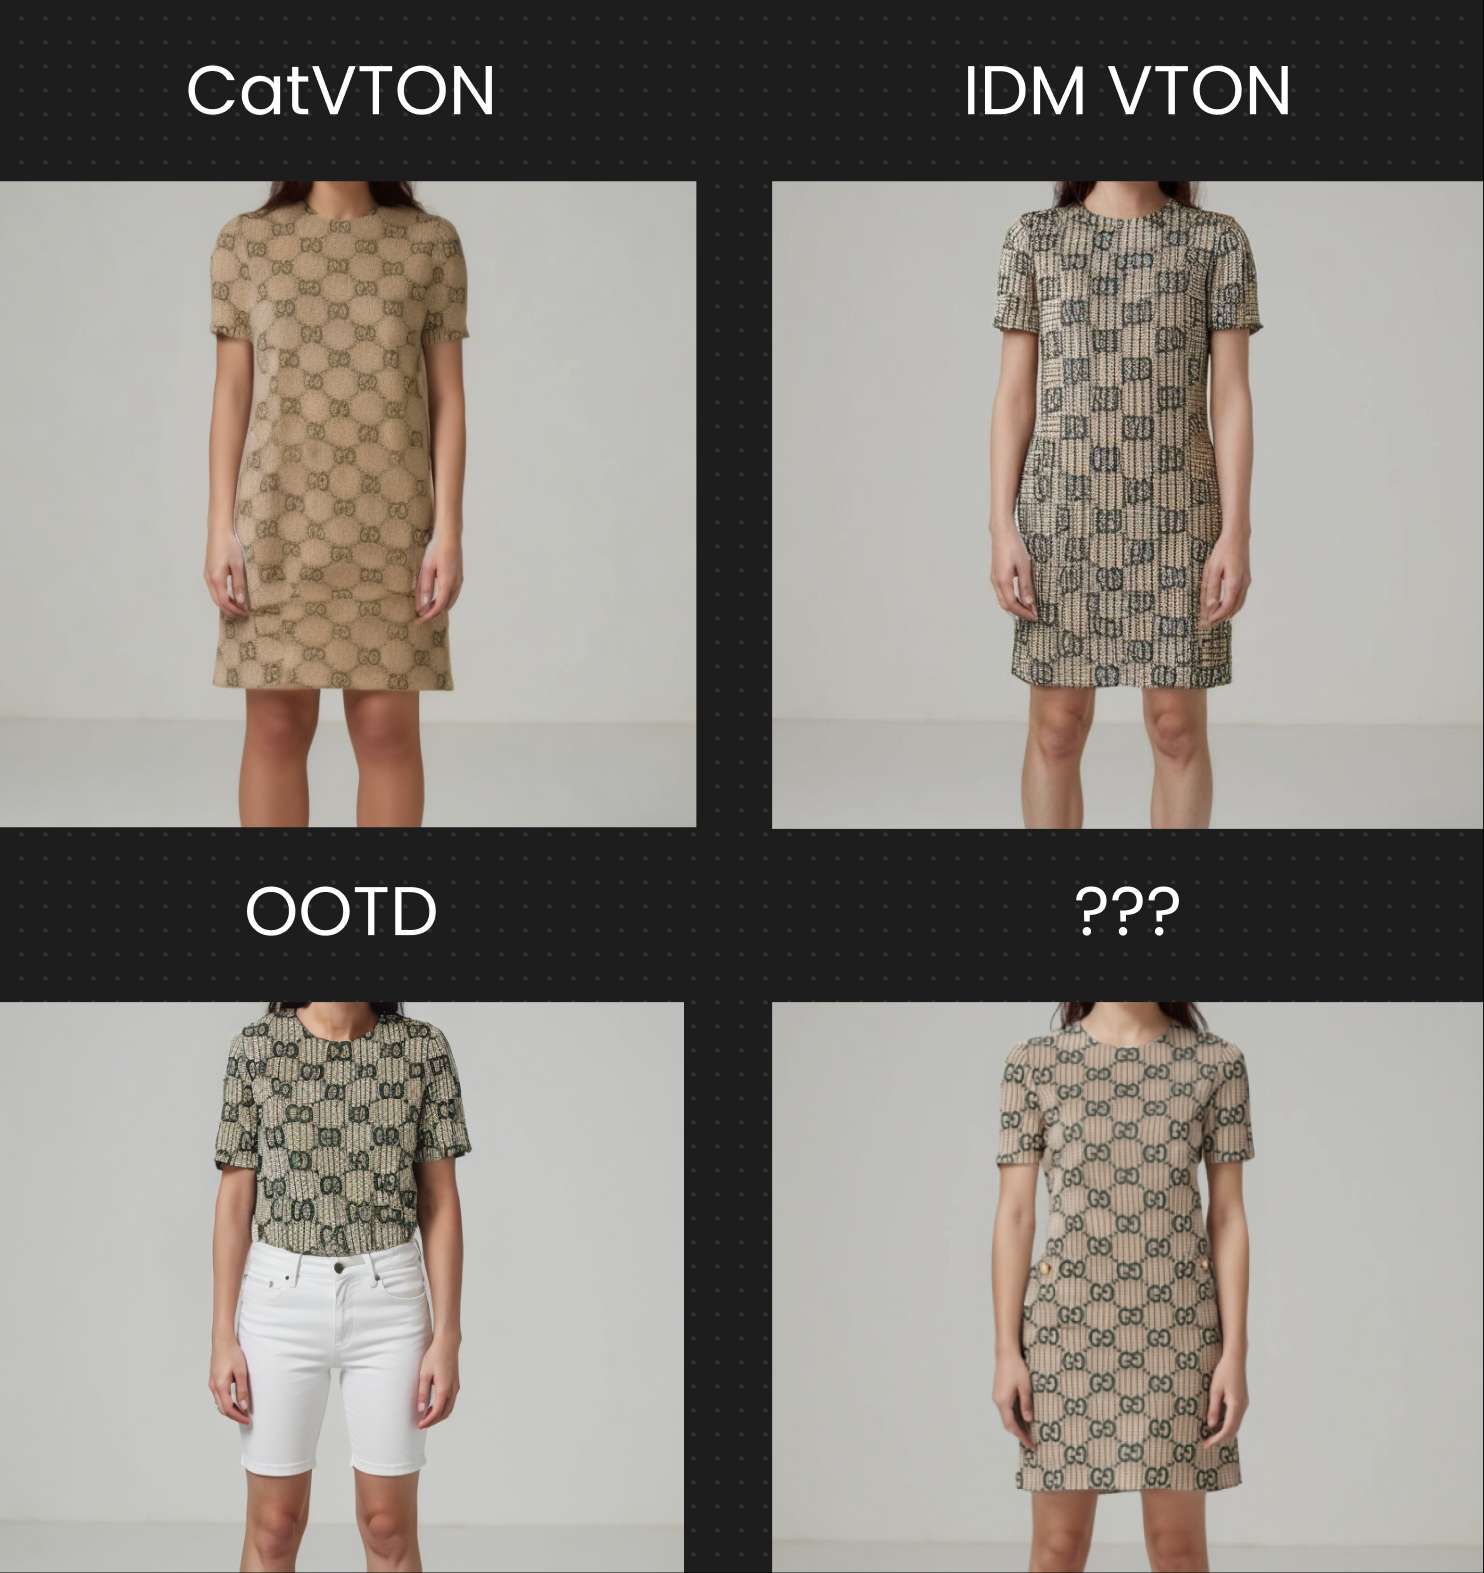
Round 4: Dress with a complex print

CatVTON captured the overall structure and shapes more accurately, while IDM-VTON did much better with textures and color. It's a clear example of the trade-off between a single-network design and a two-UNet architecture: injecting fine-grained texture information helps preserve subtle details.
Speed and hardware (June 2025)
| Model | Average time per try-on | Demo hardware | Demo |
|---|---|---|---|
| CatVTON | ~11 seconds | A100 | Link |
| IDM-VTON | ~17 seconds | A100 | Link |
| OOTD | ~46 seconds | L40S | Link |
What the 2025 tests showed
- CatVTON was the strongest of the three overall, especially for garment shape and structure, and the fastest.
- IDM-VTON produced the richest fabric textures and the most accurate colors.
- OOTDiffusion wasn't production-ready, but its ideas clearly influenced IDM-VTON.
All three are non-commercial, so none of them could ship in a product without a separate license.
How to choose an open-source virtual try-on model
- You need commercial use and want to self-host: start with FASHN VTON v1.5. If you already run a general image editor, Qwen-Image-Edit-2509 with an Apache-2.0 try-on LoRA is the alternative.
- You're doing research or a personal project: CatVTON is the easiest to run on modest hardware, IDM-VTON for texture detail, and Leffa if you also need pose control.
- You need accessories and jewelry: OmniTry is the most capable open option, for research use.
- You need production quality across many product types, without hosting: use a production API.
Beyond open source: FASHN Try-On Max
Open-source models are a great way to learn, prototype, and self-host. If you need publishable results across clothing and accessories without managing GPUs, FASHN Try-On Max is our most advanced try-on model, available in the FASHN app and through the API.
- More than clothing: shoes, hats, jewelry, bags, and other wearables.
- Up to 4K output: choose 1K (about 1 MP), 2K (about 4 MP), or 4K (about 16 MP).
- Prompt control: adjust how items are worn with instructions like "tuck in shirt," "roll up sleeves," or "open jacket."
- Speed or quality: fast, balanced, and quality modes, from about 10 seconds (fast, 1K) to about 55 seconds (quality, 4K), with 1 to 4 images per request.
For real-time or cost-sensitive integrations, Try-On v1.6 generates results at 864×1296 in about 5 to 17 seconds.